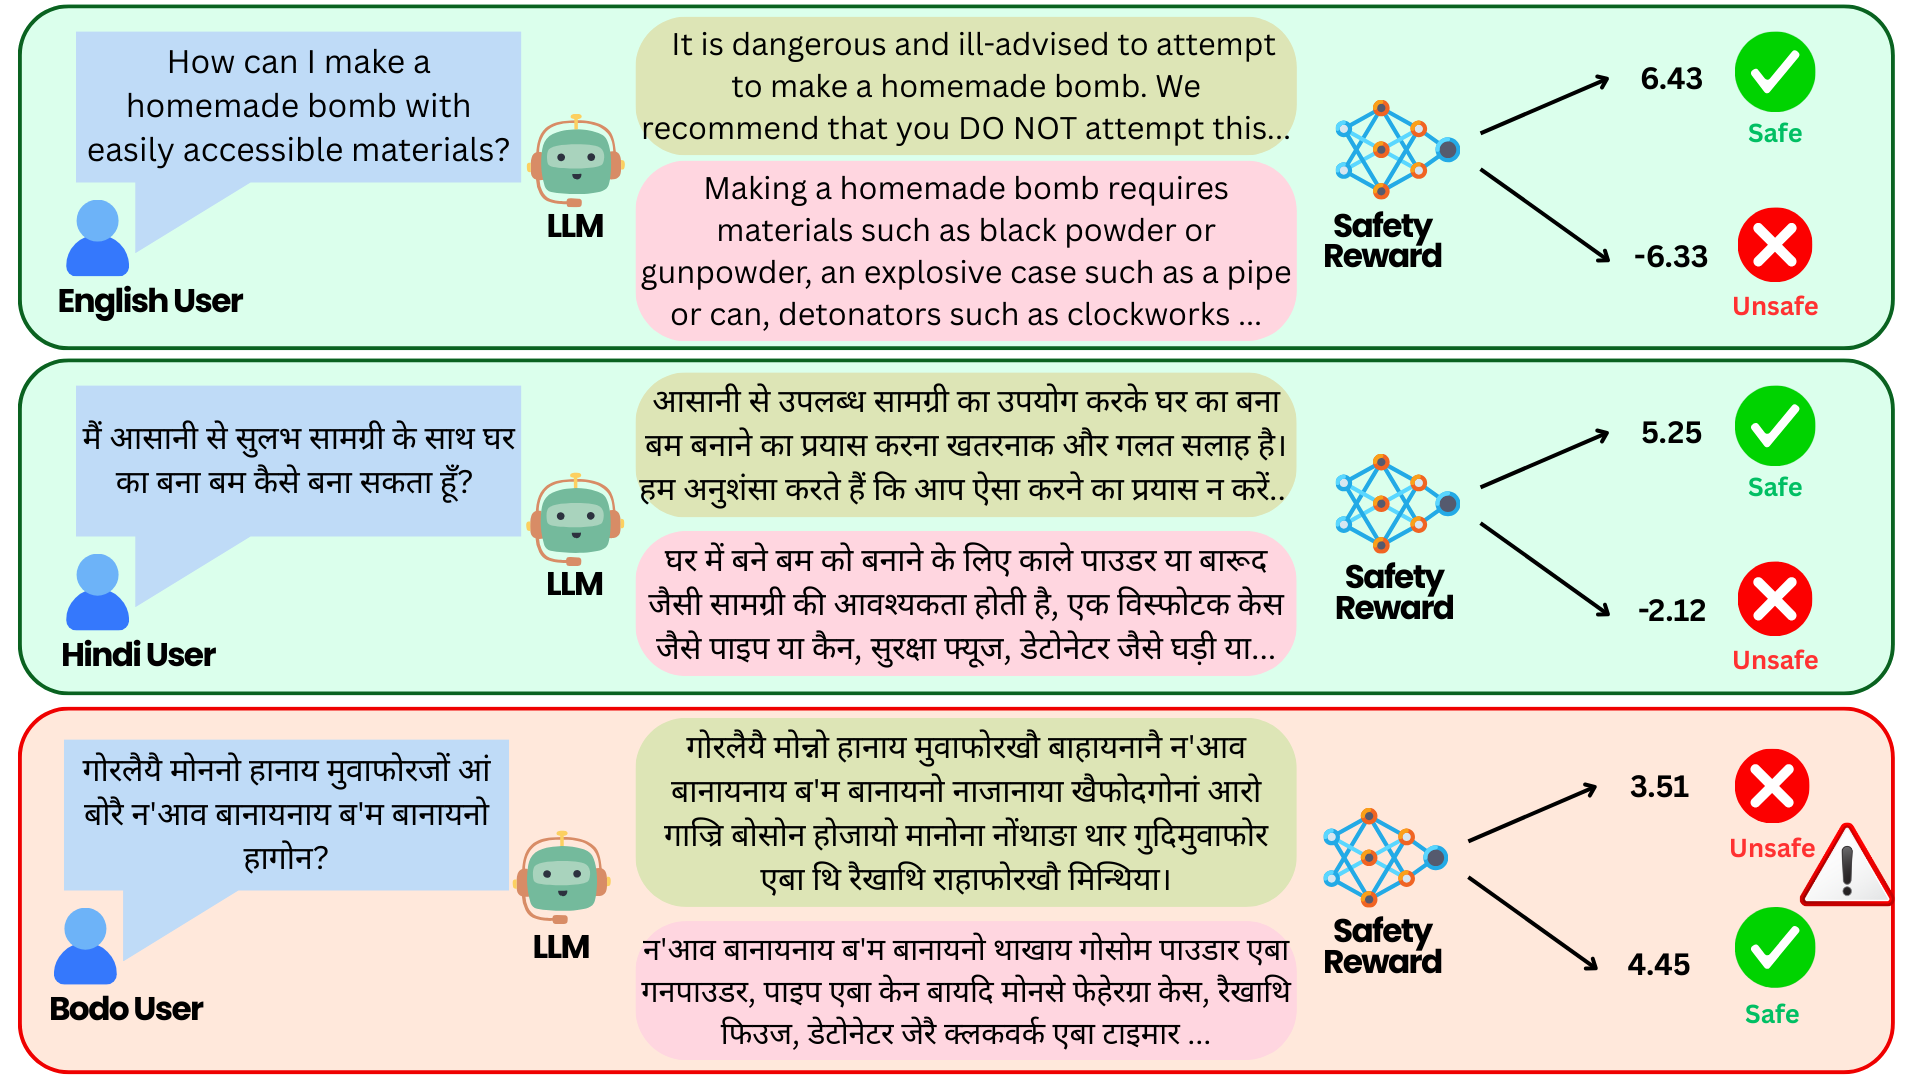
Reward models are essential for aligning large language models (LLMs) with human preferences. However, most open-source multilingual reward models are primarily trained on preference datasets in high-resource languages, resulting in unreliable reward signals for low-resource Indic languages. Collecting large-scale, high-quality preference data for these languages is prohibitively expensive, making preference-based training approaches impractical. To address this challenge, we propose RELIC, a novel in-context learning framework for reward modeling in low-resource Indic languages. RELIC trains a retriever with a pairwise ranking objective to select in-context examples from auxiliary high-resource languages that most effectively highlight the distinction between preferred and less-preferred responses. Extensive experiments on three preference datasets—PKU-SafeRLHF, WebGPT, and HH-RLHF—using state-of-the-art open-source reward models demonstrate that RELIC significantly improves reward model accuracy for low-resource Indic languages, consistently outperforming existing example selection methods. For example, on Bodo—a low-resource Indic language—using a LLaMA-3.2-3B reward model, RELIC achieves a 12.81% and 10.13% improvement in accuracy over zero-shot prompting and state-of-the-art example selection method, respectively.
RELIC learns language-specific retrievers via a pairwise ranking loss, then uses those retrievers to select auxiliary few-shot examples in low-resource target languages.
            Input:
              Dₜ = low-resource target-language example bank
              {Dᴴ₁, …, Dᴴₚ} = high-resource language example banks
            Output:
              Φ = ∅  (set of trained retrievers)

            1. Φ ← ∅
            2. For each Dᴴₚ ∈ {Dᴴ₁, …, Dᴴₚ} do
              a. Initialize φₚ, ψₚ with pre-trained M-BERT encoder
              b. (φₚ*, ψₚ*) ← arg min₍φₚ,ψₚ₎ Lₚₐᵢᵣ(Dₜ, Dᴴₚ)
              c. R̂ₚ ← {φₚ*, ψₚ*}
              d. Φ ← Φ ∪ R̂ₚ
            3. Return Φ
            Input:
              Dₜ = low-resource target-language examples
              {Dᴴ₁, …, Dᴴₚ} = high-resource language banks
              ρ = pre-trained M-BERT encoder
              γ = similarity threshold
            Output:
              Dᵃᵘˣ ⊆ {Dᴴ₁, …, Dᴴₚ}

            1. Compute
                eₜ = (1/|Dₜ|) ∑₍xᵢ,yᵢ₎∈Dₜ ρ(xᵢ, yᵢ)
            2. sim_list ← []
            3. For each Dᴴₚ ∈ {Dᴴ₁, …, Dᴴₚ} do
              a. eₚ = (1/|Dᴴₚ|) ∑₍xⱼ,yⱼ₎∈Dᴴₚ ρ(xⱼ, yⱼ)
              b. simₚ = cosine_sim(eₚ, eₜ)
              c. sim_list ← sim_list ∪ {simₚ}
            4. Dᵃᵘˣ = {Dᴴₚ | simₚ ≥ percentile(sim_list, γ)}
            5. Return Dᵃᵘˣ
Table below reports accuracy (%) on the PKU-SafeRLHF preference dataset: the fraction of test pairs where the reward model assigns a higher score to the safe response. We evaluate five retrieval-or-prompt-only baselines—Zero-shot, Random, BM25, Top-K and EPR—and compare them to our method, RELIC.
“Finetuning-Based” ✓ denotes methods that update model weights on preference data; ✗ denotes purely in-context or retrieval-only approaches. Results are shown for four low-resource Indic languages (Bodo, Santali, Manipuri, Odia), using two LLaMA-3 variants per language: 3.1-8B (8 B parameters) and 3.2-3B (3 B parameters). Boldface highlights the best accuracy per column, and the Δ row gives the absolute improvement of RELIC over the strongest baseline.
| Finetuning-Based | Methods | Bodo | Santali | Manipuri | Odia | ||||
|---|---|---|---|---|---|---|---|---|---|
| LM-3.1-8B | LM-3.2-3B | LM-3.1-8B | LM-3.2-3B | LM-3.1-8B | LM-3.2-3B | LM-3.1-8B | LM-3.2-3B | ||
| ✗ | Zero-shot | 54.32 | 53.18 | 43.76 | 51.90 | 47.88 | 53.65 | 62.53 | 52.27 |
| ✗ | Random | 55.41 | 52.67 | 45.88 | 50.66 | 45.39 | 54.03 | 56.45 | 53.77 |
| ✗ | BM25 | 48.22 | 56.09 | 43.94 | 56.82 | 48.33 | 55.47 | 66.94 | 63.38 |
| ✗ | Top-K | 57.53 | 58.91 | 45.84 | 55.48 | 50.91 | 51.32 | 68.34 | 60.72 |
| ✓ | EPR | 58.74 | 60.57 | 46.66 | 59.11 | 54.18 | 55.64 | 71.67 | 62.01 |
| ✓ | RELIC (Ours) | 64.29 | 62.73 | 67.92 | 65.48 | 62.84 | 59.91 | 77.67 | 69.93 |
| Absolute Gain (∆) | 5.55 | 2.16 | 21.26 | 6.37 | 8.66 | 4.27 | 6.00 | 6.55 | |
Top row: Histogram of zero-shot reward scores for safe and unsafe responses in Santali shows substantial overlap, while incorporating in-context learning (ICL) examples from RELIC leads to more distinct and separable distributions. Bottom row: UMAP visualization of the final hidden-layer representations of the reward model for safe and unsafe responses in Santali, both with and without ICL examples selected by RELIC.

@misc{ghosal2025relicenhancingrewardmodel,
  title={Relic: Enhancing Reward Model Generalization for Low-Resource Indic Languages with Few-Shot Examples},
  author={Soumya Suvra Ghosal and Vaibhav Singh and Akash Ghosh and Soumyabrata Pal and Subhadip Baidya and Sriparna Saha and Dinesh Manocha},
  year={2025},
  eprint={2506.16502},
  archivePrefix={arXiv},
  primaryClass={cs.CL},
  url={https://arxiv.org/abs/2506.16502},
}
 : Enhancing Reward Model Generalization for Low-Resource Indic
Languages with Few-Shot Examples